Multimodal Input Capabilities in Microsoft Foundry
Short answer
1: Yes; 2: No; 3: No
Question
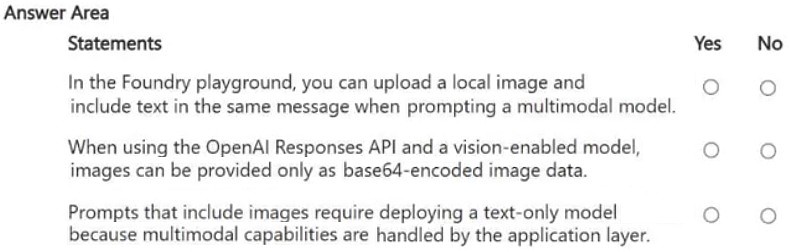
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Key Takeaways
The main trap is assuming strict input formats (like base64-only) or architectural dependencies (separate model deployment) that do not exist in modern multimodal APIs.
This page explains why multimodal models in Microsoft Foundry accept combined image-text prompts, how the OpenAI API supports both base64 and URL image inputs, and why separate text model deployment is unnecessary.
Common mistake: Learners often incorrectly assume that vision models require separate text models or that image inputs are limited to base64 encoding, failing to recognize the unified nature of multimodal endpoints.
Expert Analysis
The question tests the capabilities of multimodal models within Microsoft Foundry and the OpenAI Responses API. The first statement is true because vision-enabled models in the playground support multimodal inputs, allowing users to combine local image uploads with text prompts. This confirms the model's ability to process both visual and textual data simultaneously.
The second statement is false. While base64-encoded images are a valid input method for the OpenAI Responses API, they are not the only option. The API also accepts publicly accessible HTTP URLs as image sources. Restricting input to only base64 encoding is incorrect.
The third statement is false. Deploying a separate text-only model is not a prerequisite for using prompts that include images. Modern multimodal architectures handle both modalities within a single model instance, eliminating the need for separate deployments or complex orchestration between distinct text and vision models.
Official Reference
- https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/
- https://platform.openai.com/docs/guides/vision
These links open the official vendor documentation in a new tab.
Exam Strategy
When evaluating AI service capabilities, always consider whether the platform offers unified multimodal solutions versus modular components. Look for keywords like 'multimodal' or 'vision-enabled' which typically imply integrated processing, reducing the need for separate infrastructure or rigid input constraints.
Frequently Asked Questions
Can I use HTTP URLs instead of base64 for images in OpenAI API?
Do I need a separate text model to process text with an image?
Discussion 1 contributions
Compiled from public community threads and reader submissions, lightly edited for clarity. Handles and vote tallies are shown as recorded, and comments reflect the views of individual contributors.
From public community threads 1
-
GrandWizard_007 👍 11. Yes - in the Microsoft Foundry playground, you can upload a local image and include text in the same prompt when using a vision‑enabled (multimodal) model. 2. No - It is false that vision‑enabled models in the OpenAI Responses API only accept base64‑encoded images — you can also pass images as publicly accessible HTTP URLs. 3. No - Prompts that include images do not require you to deploy a text‑only model; many modern systems are natively multimodal and can process both text and images directly, without needing to convert the image into text first
Reader comments & corrections
No reader corrections yet — spotted an error or have a note? Share it below.
Related Analysis
Practice All AI-901 Questions
Access 105 questions with complete answers and detailed explanations.
View Full AI-901 Practice Test →