Multimodal Generative AI Capabilities in Azure Foundry
Short answer
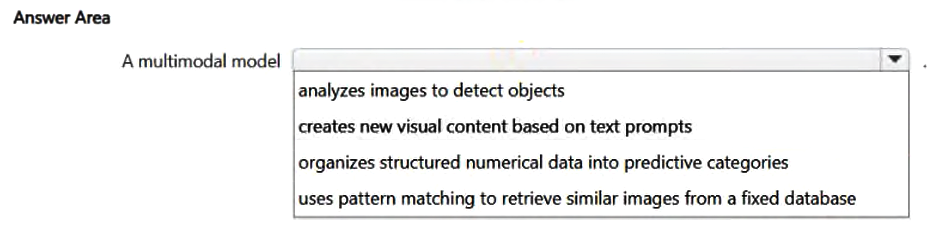
The correct choice is the option stating: Creates new visual content based on text prompts. This represents the core function of multimodal generative AI models.
Question
Select the answer that correctly completes the sentence.
Key Takeaways
The trap lies in confusing 'analyzing' existing images (Computer Vision) with 'creating' new ones (Generative AI); the correct answer identifies text-to-image generation as a multimodal task.
This question tests the ability to distinguish between computer vision object detection and multimodal generative image creation. It establishes that generating new visual content from text prompts is a core capability of multimodal generative AI models.
Common mistake: Learners often select 'Analyzes images to detect objects' because it involves both text and vision, but this is a discriminative task (classification/detection), not a generative one.
Expert Analysis
Why the Answer Is Correct
The correct completion for the sentence is the option describing: "Creates new visual content based on text prompts." This accurately defines the function of a multimodal generative AI model, such as DALL-E or Stable Diffusion integrated into Azure Foundry. These models take natural language input (text) and generate corresponding output (images), which fits the definition of multimodal interaction.
Why Other Candidate Answers Are Wrong
"Analyzes images to detect objects" describes Computer Vision tasks like object detection or image classification. While these may use pre-trained models, they do not generate new content; they interpret existing data. "Organizes structured numerical data" refers to traditional predictive machine learning (regression/classification). "Uses pattern matching" is too vague and often associated with rule-based systems or simple search, not generative AI.
Community Comment Notes
Community consensus correctly identifies option B as the answer. As user BabiRahul noted, creating new visual content is the key differentiator. Another commenter, Sr18, clarified that while multimodel can do detection, vision-specific models are better suited for that, reinforcing that generation is the unique generative trait here.
Exam Strategy
When answering questions about AI capabilities, always distinguish between 'Perception' (understanding input like CV) and 'Generation' (creating output like GenAI). If the prompt mentions 'creating', 'synthesizing', or 'generating' new media from text, it is likely Multimodal Generative AI.
Frequently Asked Questions
What is the difference between Computer Vision and Multimodal Generative AI?
Can multimodal models perform object detection?
Discussion 2 contributions
Compiled from public community threads and reader submissions, lightly edited for clarity. Handles and vote tallies are shown as recorded, and comments reflect the views of individual contributors.
From public community threads 2
-
BabiRahul 👍 1B Why the other options are incorrect: Analyzes images to detect objects → This is primarily a computer vision/object detection task. Creates new visual content based on text prompts → ✅ Correct. A multimodal generative AI model can generate images from text descriptions. Organizes structured numerical data into predictive categories → This is a classification machine learning task. Uses pattern matching to retrieve similar images from a fixed database → This is image retrieval/search, not multimodal generation.
-
Sr18 👍 1B Object detection can be achieved by multimodel but vision is better suited for that task.
Reader comments & corrections
No reader corrections yet — spotted an error or have a note? Share it below.
Related Analysis
Practice All AI-901 Questions
Access 105 questions with complete answers and detailed explanations.
View Full AI-901 Practice Test →