Does Removing the Salesperson Table Meet Model1's Size Goal?
Short answer
A Removing the redundant Salesperson table from Model1 preserves SalespersonID and CityID in Sales for sales-by-salesperson-per-city analysis.
Question
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You are creating a Power BI semantic model named Model1 that contains the following tables.
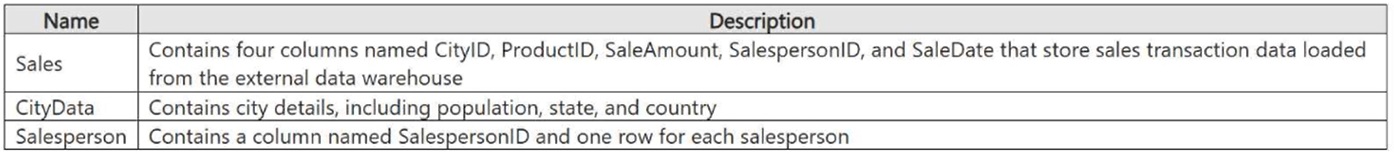
The tables have the following relationships.
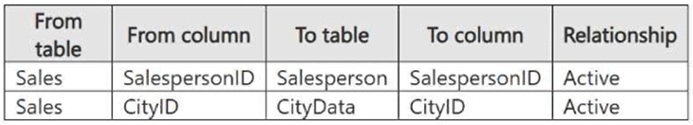
You have 100 salespeople in 10,000 cities. Each salesperson sells in multiple cities.
You import one million rows into the Sales table.
You need to reduce the size of Model1. The solution must ensure that you can analyze the total number of sales by salesperson per city.
Solution: You remove the Salesperson table.
Does this meet the goal?
Key Takeaways
The question tests whether a dimension table is required when its key already exists in the fact table; the trap is assuming every SalespersonID needs a separate table.
In this PL-300 scenario, Model1's Sales fact table already stores both SalespersonID and CityID, so removing the redundant one-column Salesperson dimension still allows total sales to be analyzed by salesperson per city while reducing model size.
Common mistake: The most common wrong answer is No, because candidates assume removing the Salesperson table loses the ability to analyze salesperson performance, even though Sales[SalespersonID] remains available for grouping and filtering.
Expert Analysis
Why the Answer Is Correct
Removing the Salesperson table meets the goal because the Sales table already contains SalespersonID and CityID, which are the keys needed to analyze total sales by salesperson per city. The Salesperson table, as described in the scenario, adds only SalespersonID and no descriptive salesperson attributes. A matrix visual can group Sales[SalespersonID] against City[CityID] or City[City] without the redundant dimension. Therefore, the solution reduces Model1 by eliminating an unnecessary table and relationship while preserving the required analysis.
Why the Other Options Are Wrong
Choosing No incorrectly assumes that the Salesperson dimension supplies data needed for the required analysis. Because Sales still has SalespersonID, users can still filter and group fact rows by salesperson. Losing a textbook star-schema dimension is not fatal for this specific requirement, especially when the dimension is a single key column. The only case where No would be right is if the Salesperson table contained additional attributes such as salesperson name or region that the report required, but those attributes are not part of this scenario.
Community Comment Notes
As nikisychan noted, the Salesperson table "only contains a single column: SalespersonID" and is redundant because that key already exists in Sales. e68b25f made the same key point: the Sales table "has both column SalespersonID and CityID", so the required grouping is possible from the fact table. Idaresit worried about losing salesperson names and star-schema structure, but names are not part of the described Salesperson table, and the exam question asks whether the solution meets the goal rather than whether it is the most elegant model design.
Official Reference
- https://learn.microsoft.com/en-us/power-bi/guidance/star-schema
- https://learn.microsoft.com/en-us/power-bi/guidance/import-modeling-data-reduction
These links open the official vendor documentation in a new tab.
Exam Strategy
Separate the need to reduce model size from the need to preserve the exact report fields. If the fact table already contains the keys used for grouping and filtering, removing a one-column dimension is usually valid even if the size saving is small.
Frequently Asked Questions
Why is removing the Salesperson table acceptable when analyzing sales by salesperson?
Does dropping a 100-row dimension really reduce Model1's size?
Discussion 4 contributions
Compiled from public community threads and reader submissions, lightly edited for clarity. Handles and vote tallies are shown as recorded, and comments reflect the views of individual contributors.
From public community threads 4
-
nikisychan 👍 2 Answered ABased on the provided table descriptions, the Salesperson table only contains a single column: SalespersonID. Because the SalespersonID column already exists in the Sales fact table, the Salesperson dimension table is completely redundant—it provides no additional descriptive attributes (such as salesperson name, region, or manager). Removing this table will reduce the overall size of the semantic model by eliminating the table's footprint and the overhead of the relationship. You will still be able to meet the analytical goal of analyzing sales by salesperson per city by simply using the SalespersonID column directly from the Sales table alongside the CityData table.
-
Idaresit 👍 1f you remove Salesperson table: You lose: The ability to group Sales by salesperson name or ID from a dimension A proper star schema structure Optimized filtering via dimension table But more importantly: You do NOT significantly reduce model size in a meaningful way (because the Sales table is still the dominant size driver with a million rows, salesperson has only a 100 rows)
-
Idaresit 👍 1 Answered BThe Salesperson table gives more information about the salesperson ID e.g. their names. I don't think presenting a report without names is interesting enough.
-
e68b25f 👍 1 Answered ASales table has both column SalespersonID and CityID
Reader comments & corrections
No reader corrections yet — spotted an error or have a note? Share it below.
Related Analysis
Practice All PL-300 Questions
Access 116 questions with complete answers and detailed explanations.
View Full PL-300 Practice Test →