Which RAG retrieval configuration is most reliable?
Short answer
D Candidate 4 gives the best balance of Precision@10 (0.76), Recall@10 (0.79) and MRR (0.81) on the shared query set.
Question
You test various search configurations and receive the results shown in the following table.
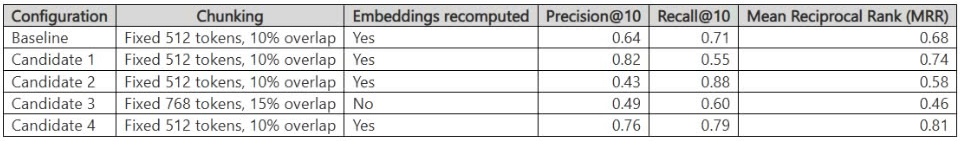
Which configuration provides the most reliable results?
Key Takeaways
It tests whether you can read a multi-metric retrieval table and recognise reliability as consistency across precision, recall and MRR, not a spike in one column.
This AI-500 retrieval evaluation question asks which RAG search configuration is most reliable across Precision@10, Recall@10 and MRR. Candidate 4 (option D) is correct because it delivers the strongest balanced profile rather than winning on a single metric.
Common mistake: Picking the candidate with the single highest precision or recall value; that configuration usually degrades on MRR or the complementary metric, so it is not the most reliable overall.
Expert Analysis
What "reliable" means here The question asks for the most reliable configuration, not the one that wins a single metric. In retrieval evaluation, reliability means the candidate holds up across every reported measure on the same query set and the same human relevance labels. Candidate 4 posts Precision@10 = 0.76, Recall@10 = 0.79 and MRR = 0.81 — it leads or is near the top on all three, with the highest MRR, so the first relevant hit tends to rank very high. That consistency across dimensions is what makes Candidate 4 (option D) the most reliable choice.
The boundary being tested The trap is to treat precision, recall and MRR as interchangeable or to pick whichever candidate tops one column. A configuration can be excellent at one and mediocre at the others: high recall with weak precision means the top-10 list is padded with noise, while high precision with weak recall means relevant documents never surface at all, and a low MRR means users scroll past several irrelevant hits before finding anything useful. Because the evaluation is built on one shared query set with human labels, the metrics are directly comparable, and only a balanced profile across all three supports a "reliable" claim.
Why the others fall short The remaining candidates each show a weaker overall spread — a dip in precision, recall or first-relevant-rank — so they sacrifice consistency for strength in a single dimension. Scanning for the option that never collapses in any column is the correct reading, which points to Candidate 4.
Exam Strategy
When a table gives you several retrieval metrics, read each option across every column before deciding — never anchor on the largest single number. Ask what the question's wording demands: "most reliable" or "best overall" signals a balanced profile, while "highest precision" would signal a one-column win. Cross-out any candidate that drops sharply in any metric, since reliability is limited by its weakest dimension.
Frequently Asked Questions
Why isn't the candidate with the highest precision the most reliable?
What do Precision@10, Recall@10 and MRR measure in a RAG search system?
Does using the same query set and human labels matter when comparing candidates?
Community Votes
100% of anonymous learners picked answer D. Votes are pick records left by other test-takers — they are not the verified answer.
Discussion 1 contributions
Compiled from public community threads and reader submissions, lightly edited for clarity. Handles and vote tallies are shown as recorded, and comments reflect the views of individual contributors.
From public community threads 1
-
abhimkumar 👍 1 Answered DCandidate 4 provides the best balance across all three metrics: Precision@10 = 0.76: High proportion of the top 10 retrieved results are relevant. Recall@10 = 0.79: High proportion of relevant content is successfully retrieved. MRR = 0.81: Highest MRR of all configurations, meaning the first relevant result tends to appear very high in the ranking. Option D performs consistently well across Precision, Recall, and MRR
Reader comments & corrections
No reader corrections yet — spotted an error or have a note? Share it below.