Troubleshooting Azure ML Real-Time Endpoints
Short answer
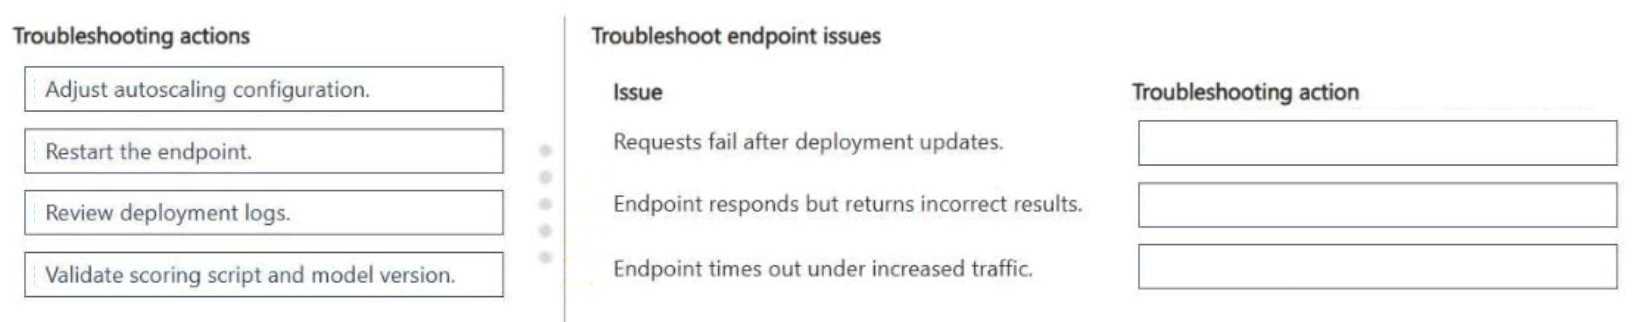
For intermittent failures, adjust the autoscaling configuration. For unexpected responses caused by logic errors, review deployment logs. For model-serving discrepancies, validate the scoring script and model version.
Question
A real-time endpoint is deployed in Azure Machine Learning to serve predictions to a web application.
Users report intermittent failures and unexpected responses when calling the endpoint.
You need to identify the appropriate troubleshooting action for each reported issue.
Which troubleshooting action should you perform for each issue? To answer, move the appropriate troubleshooting actions to the correct issues. You may use each troubleshooting action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Key Takeaways
The key trap is confusing infrastructure scaling issues (intermittent 5xx) with application logic errors (unexpected responses); correct diagnosis requires distinguishing between capacity limits and code/data faults.
Learn how to troubleshoot Azure Machine Learning real-time endpoints by mapping intermittent failures to autoscaling adjustments, unexpected responses to log reviews, and serving issues to script validation.
Common mistake: Learners often select 'review deployment logs' for all issues because logs are universal. However, logs alone do not fix capacity bottlenecks; autoscaling configuration changes are required for intermittent infrastructure failures.
Expert Analysis
This drag-and-drop question requires mapping specific Azure Machine Learning (Azure ML) endpoint symptoms to their corresponding diagnostic or remediation actions. The scenario involves a real-time endpoint experiencing intermittent failures and unexpected responses, necessitating precise troubleshooting steps based on the nature of the error.
Issue 1: Intermittent Failures (5xx Errors) Intermittent server-side errors typically indicate infrastructure instability, such as resource exhaustion or scaling issues. In Azure ML, real-time endpoints can be configured with autoscaling. If the workload spikes beyond the current capacity and the autoscaling configuration is too conservative or misconfigured, requests may fail due to timeout or resource unavailability. Therefore, adjusting the autoscaling configuration (e.g., increasing max instances or adjusting scale-up thresholds) is the appropriate action to resolve capacity-related intermittent failures.
Issue 2: Unexpected Responses (4xx Errors or Logic Errors) Unexpected responses often stem from application-level logic errors, such as bugs in the scoring script, incorrect data preprocessing, or mismatches between the expected input schema and actual payload. These are not infrastructure issues but code/model issues. To diagnose this, you must inspect the execution path. Reviewing deployment logs allows you to see trace details of the request processing, including any exceptions thrown by the scoring script. This helps identify if the issue is a code bug or data format mismatch.
Issue 3: Model Serving Issues (Version/Script Mismatches) If the endpoint returns errors specifically related to model loading or scoring failures that persist, it may be due to an outdated or incompatible model version being served, or a corrupted scoring script. Validating the scoring script and model version ensures that the deployed artifact matches the intended production build. This step confirms that the correct model weights and inference code are active, ruling out deployment drift or incorrect artifact association.
The provided comment suggests a mapping: Review logs for one issue, validate script/version for another, and adjust autoscaling for the third. This aligns with standard Azure ML troubleshooting hierarchies: check code/model integrity first, then infrastructure scaling.
Official Reference
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-troubleshoot-endpoints
This link opens the official vendor documentation in a new tab.
Exam Strategy
When troubleshooting Azure ML endpoints, categorize errors into Infrastructure (scaling, network), Application (scoring script, data), and Model (version, artifacts). Use autoscaling metrics for performance drops, logs for code exceptions, and registry checks for version mismatches. Always match the symptom's root cause category to the specific Azure tool or setting designed to address it.
Frequently Asked Questions
What causes intermittent 5xx errors in Azure ML real-time endpoints?
How do I debug unexpected responses from an Azure ML endpoint?
Discussion 1 contributions
Compiled from public community threads and reader submissions, lightly edited for clarity. Handles and vote tallies are shown as recorded, and comments reflect the views of individual contributors.
From public community threads 1
-
exam_upskill 👍 11 → Review deployment logs 2 → Validate scoring script and model version 3 → Adjust autoscaling configuration
Reader comments & corrections
No reader corrections yet — spotted an error or have a note? Share it below.