How Do You Stream Change Data Feed Inserts, Updates and Deletes from a Delta Table?
HOTSPOT
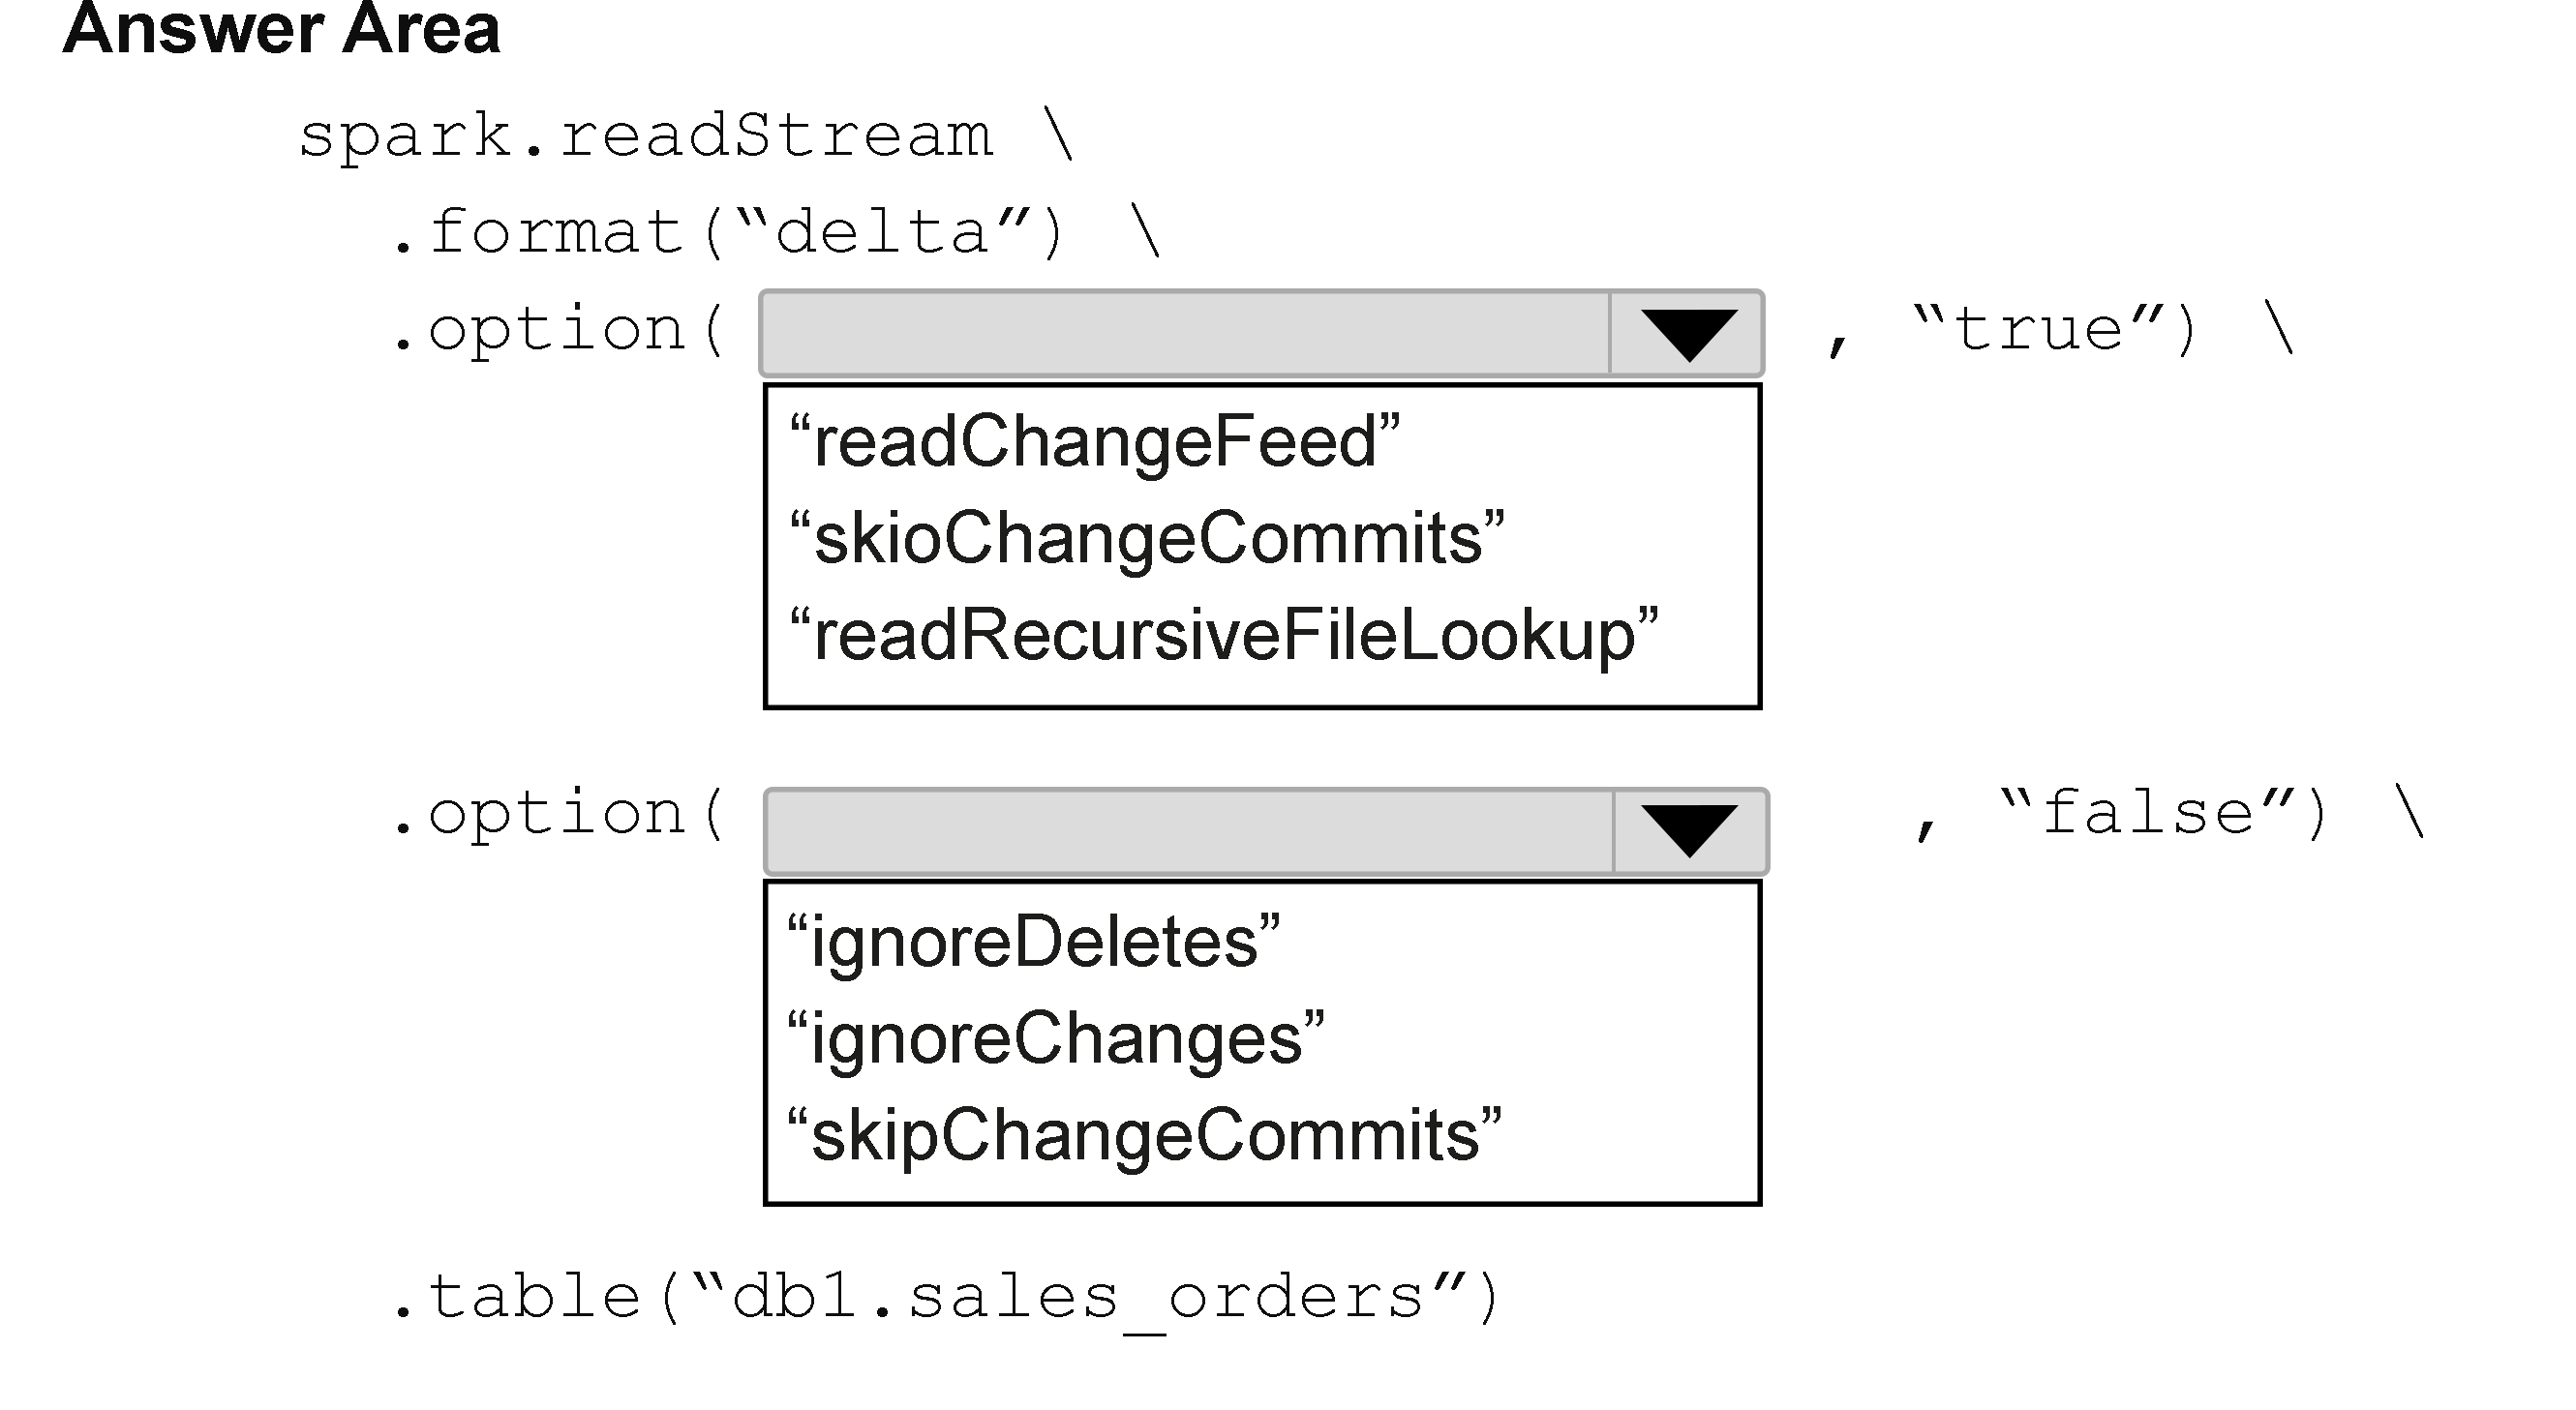
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
db1.sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the db1.sales_orders table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Community Insight
The item tests whether you can wire a Unity Catalog Delta table's change data feed into PySpark Structured Streaming; the trap is selecting the deprecated ignoreChanges option or setting skipChangeCommits = true, which silently drops deletes and updates.
Reading change data feed from db1.sales_orders requires readChangeFeed = true on the streaming read, which emits insert, update_preimage, update_postimage and delete change rows into the downstream pipeline. This page confirms the exact PySpark options the DP-750 hotspot expects and why the legacy ignoreChanges option breaks the stream.
Choosing ignoreChanges = true because the name suggests it captures updates. ignoreChanges is a legacy Delta streaming option that conflicts with readChangeFeed and raises an error, and skipChangeCommits = true would let non-append commits be skipped instead of surfaced as change rows.
Community Discussion (1 comments)
Comments & Corrections
No comments yet — spotted an error or have a note? Share it below.
Expert Analysis
Why the Answer Is Correct
For db1.sales_orders, CDF is already enabled on the table, so the only work left is on the reader side: the hotspot expectsreadChangeFeed = true on the streaming read so Delta emits change rows tagged with _change_type rather than just the latest snapshot. The accompanying option must be skipChangeCommits = false, which is the default and tells the stream to fail loudly on commits that rewrite data instead of quietly skipping them, so no insert, update_preimage/update_postimage pair, or delete is lost. Because the downstream pipeline must apply all three DML outcomes, both selections work together: readChangeFeed = true produces the deletes and updates, and skipChangeCommits = false guarantees they are not filtered out. The resulting stream can then be consumed with spark.readStream.option("readChangeFeed", "true").table("db1.sales_orders") and landed into a bronze table that preserves the change metadata.Why Other Candidate Answers Are Wrong
ignoreChanges = true looks attractive because it is an older option that made rewritten files reappear as new rows, but it was replaced by skipChangeCommits and Databricks explicitly rejects combining it with readChangeFeed = true, producing a stream-analysis error instead of change rows. Setting skipChangeCommits = true is equally wrong here: it suppresses commits that delete or rewrite data (for example OPTIMIZE or overwrite operations), so the deletes the pipeline must ingest would never arrive. Selecting readChangeFeed = false, or omitting it and reading the table as a plain streaming source, yields only append-style rows and loses the preimage/postimage pairs entirely. Any answer that reads the table as a batch DataFrame snapshot also fails, because a snapshot cannot convey which rows were deleted.Community Comment Notes
As zxc01 pointed out, "it should use skipChangeCommits = false(defult setting)", which matches the vendor default and keeps every change commit visible to the stream. The same commenter warned that "ignoreChanges is old setting and don't use in new versions", and that setting it alongsidereadChangeFeed = true "will conflict... and trigger errors in stream" — a practical confirmation that the deprecated option is the designed distractor. That comment is the only substantive community input on this hotspot, and it aligns with the documented CDF behaviour, so it reinforces rather than overrides the official reading. Official Reference
Exam Strategy
Read the dropdown labels literally: Databricks keeps readChangeFeed, skipChangeCommits and the deprecated ignoreChanges in the same family, so pick the pair that produces change rows without suppressing commits. When a stem says the pipeline needs inserts, updates and deletes, no option that filters or skips commits can be correct.
Frequently Asked Questions
Why does ignoreChanges = true fail when readChangeFeed = true is set on db1.sales_orders?
The two options conflict. ignoreChanges is the deprecated Delta streaming setting and Databricks raises an error when it is combined with a CDF read; use skipChangeCommits instead.
Which _change_type values does the CDF stream emit for db1.sales_orders?
insert, update_preimage, update_postimage and delete. The preimage/postimage pair lets the downstream pipeline replay each update deterministically.