Azure SQL Indexing Strategy for Mixed OLTP and Analytics Workloads
Short answer
Support NRT analytics: Nonclustered columnstore index; Reduce read time: Nonclustered columnstore index; Index only rows matching predicate: Filtered nonclustered index.
Question
You have an Azure SQL database named SalesDB that supports an ecommerce application. SalesDB contains a table named dbo.Orders that has a clustered index on a column named OrderId.
dbo.Orders receives continuous OLTP inserts and updates during business hours.
Your analytics team runs hourly aggregate queries that scan dbo.Orders to calculate revenue trends for recent dates.
You need to improve the performance of the hourly analytics queries without significantly affecting OLTP throughput. The solution must meet the following requirements:
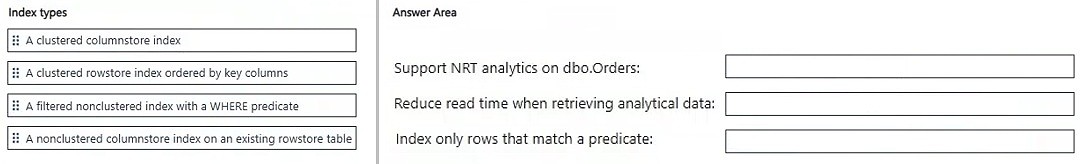
• Support near-real-time (NRT) analytics on the dbo.Orders table.
• Reduce read time when retrieving analytical data from dbo.Orders.
• Support indexing only rows that match a predicate, such as Active = 1.
Which type of index should you use for each requirement? To answer, drag the appropriate index types to the correct requirements. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Key Takeaways
The trap is assuming one index solves all problems; the key insight is that columnstore indexes handle analytical scan efficiency and concurrency, while filtered indexes handle specific row subset optimization.
Learn how to map Azure SQL index types to specific performance requirements, using nonclustered columnstore indexes for analytics and filtered indexes for predicate-based subsets.
Common mistake: Learners often select a standard clustered index or a generic nonclustered index for analytics, failing to recognize that columnstore indexes are specifically designed for analytical scan reduction and NRT capabilities in mixed workloads.
Expert Analysis
Analyze the OLTP vs. Analytics Workload Conflict
The scenario presents a classic dual-workload problem within Azure SQL Database. The dbo.Orders table serves two distinct purposes: high-frequency Online Transaction Processing (OLTP) inserts/updates and hourly analytical aggregate scans. Standard B-tree indexes optimize point lookups but degrade write performance under heavy insert loads and are inefficient for full-table or large-range scans required by analytics.
Requirement 1 & 2: Near-Real-Time Analytics and Read Reduction To support near-real-time (NRT) analytics without significantly impacting OLTP throughput, you must decouple the analytical workload from the transactional rowstore. A Nonclustered Columnstore Index is the correct architectural choice here. Columnstore indexes compress data at the column level, reducing I/O for analytical scans and enabling vectorized execution, which drastically reduces read time. Crucially, in Azure SQL Database, nonclustered columnstore indexes on rowstore tables allow concurrent OLTP operations (inserts/updates) to proceed with minimal locking contention, satisfying the NRT requirement while keeping the primary clustered index optimized for transactions.
Requirement 3: Predicate-Based Indexing
The third requirement specifies indexing only rows where Active = 1. This is a specific filtering condition applied to a subset of data. While a columnstore index scans columns, it does not inherently restrict physical storage to a single predicate value in the same efficient manner as a filtered index for specific lookups. A Filtered Nonclustered Index is designed precisely for this: it creates an index on a subset of rows defined by a WHERE clause (WHERE Active = 1). This reduces index size and maintenance overhead for the active dataset, ensuring that queries targeting only active orders are highly efficient.
Synthesis of Mappings
- Support NRT analytics: Nonclustered columnstore index
- Reduce read time: Nonclustered columnstore index
- Index only rows matching predicate: Filtered nonclustered index
Official Reference
- https://learn.microsoft.com/en-us/sql/relational-databases/indexes/nonclustered-columnstore-indexes-overview
- https://learn.microsoft.com/en-us/sql/relational-databases/indexes/create-filtered-indexes
- https://learn.microsoft.com/en-us/sql/t-sql/statements/create-index-transact-sql
These links open the official vendor documentation in a new tab.
Exam Strategy
When faced with mixed workloads, first identify the dominant query pattern for each requirement. If the requirement involves 'analytics', 'aggregates', or 'scan reduction', prioritize columnstore indexes. If the requirement involves 'subset of rows' or 'specific predicate', prioritize filtered indexes. Always check if the solution impacts OLTP throughput; columnstore indexes are preferred for NRT scenarios because they minimize lock contention compared to other analytical structures.
Frequently Asked Questions
Why not use a clustered columnstore index instead?
Can a filtered index support near-real-time analytics?
Discussion 2 contributions
Compiled from public community threads and reader submissions, lightly edited for clarity. Handles and vote tallies are shown as recorded, and comments reflect the views of individual contributors.
From public community threads 2
-
BozaXephon 👍 5Support NRT analytics on dbo.Orders: A nonclustered columnstore index on an existing rowstore table Reduce read time when retrieving analytical data: A nonclustered columnstore index on an existing rowstore table Index only rows that match a predicate: A filtered nonclustered index with a WHERE predicate
-
authemany2k 👍 1Support NRT analytics ↓ Nonclustered columnstore index Reduce analytical read time ↓ Nonclustered columnstore index Index only rows matching Active = 1 ↓ Filtered index
Reader comments & corrections
No reader corrections yet — spotted an error or have a note? Share it below.