Azure Databricks Compute Selection: Jobs vs SQL Warehouses
Short answer
Production ingestion workloads should use Jobs compute with autoscaling to ensure isolated, scheduled, and scalable execution. BI workloads should use SQL warehouses to provide fast, consistent, and concurrent SQL performance.
Question
This is a case study. Case studies are not timed separately from other exam sections. You can use as much exam time as you would like to complete each case study. However, there might be additional case studies or other exam sections. Manage your time to ensure that you can complete all the exam sections in the time provided. Pay attention to the Exam Progress at the top of the screen so you have sufficient time to complete any exam sections that follow this case study.
To answer the case study questions, you will need to reference information that is provided in the case. Case studies and associated questions might contain exhibits or other resources that provide more information about the scenario described in the case. Information provided in an individual question does not apply to the other questions in the case study.
A Review Screen will appear at the end of this case study. From the Review Screen, you can review and change your answers before you move to the next exam section. After you leave this case study, you will NOT be able to return to it.
To start the case study
To display the first question in this case study, select the “Next” button. To the left of the question, a menu provides links to information such as business requirements, the existing environment, and problem statements. Please read through all this information before answering any questions. When you are ready to answer a question, select the “Question” button to return to the question.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
• In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
• A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
• An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data
Data Environment
Contoso ingests the following operational and business data:
• Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
• Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
• Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
• External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
• ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company’s existing analytics environment has several issues:
Ingestion
• Telemetry pipelines fall behind during peak loads.
• Telemetry ingestion fails when schema drift occurs.
• Streaming pipelines reprocess events after a pipeline restarts.
Compute
• Production and development workloads run on the same all-purpose clusters.
• Production and development workloads do NOT support autoscaling or workload isolation.
Governance
• The ERP data is duplicated across systems and development teams.
• Naming conventions are inconsistent across development teams, regions, and products.
• Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
• Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names. Historical values are NOT required.
Pipeline operations
• Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
• Implement scalable data pipeline orchestration.
• Create a managed analytics catalog in Unity Catalog.
• Implement a consistent approach to creating curated datasets.
• Establish a centralized governance model across ingestion, cleansed, and curated layers.
• Grant data engineers access to the ERP tables by using minimal development effort.
• Adopt a compute strategy that isolates production workloads and supports autoscaling.
• Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
• Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
• Provide fast and consistent performance for business intelligence (BI) workloads.
• Prevent development activity from affecting production pipelines.
• Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
• Auto-scale ingestion pipelines to handle bursty workloads.
• Handle schema drift for the maintenance and telemetry data.
• Ingest file-based telemetry data by using minimal operational effort.
• Store all the ingested data in a format that supports incremental processing.
• Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
• Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
• Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
• Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
• Build curated tables that standardize business logic.
• Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
• Orchestrate multi-step ingestion and transformation workflows.
• Define a clear execution order and dependencies.
• Automatically retry failed steps and notify operators.
• Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
• Centralize the metadata catalog.
• Provide isolated development areas that follow standard naming conventions.
• Establish a consistent structure for organizing raw, cleansed, and curated data.
• Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
• Improve ingestion reliability and reduce operational effort.
• Standardize data definitions across development teams.
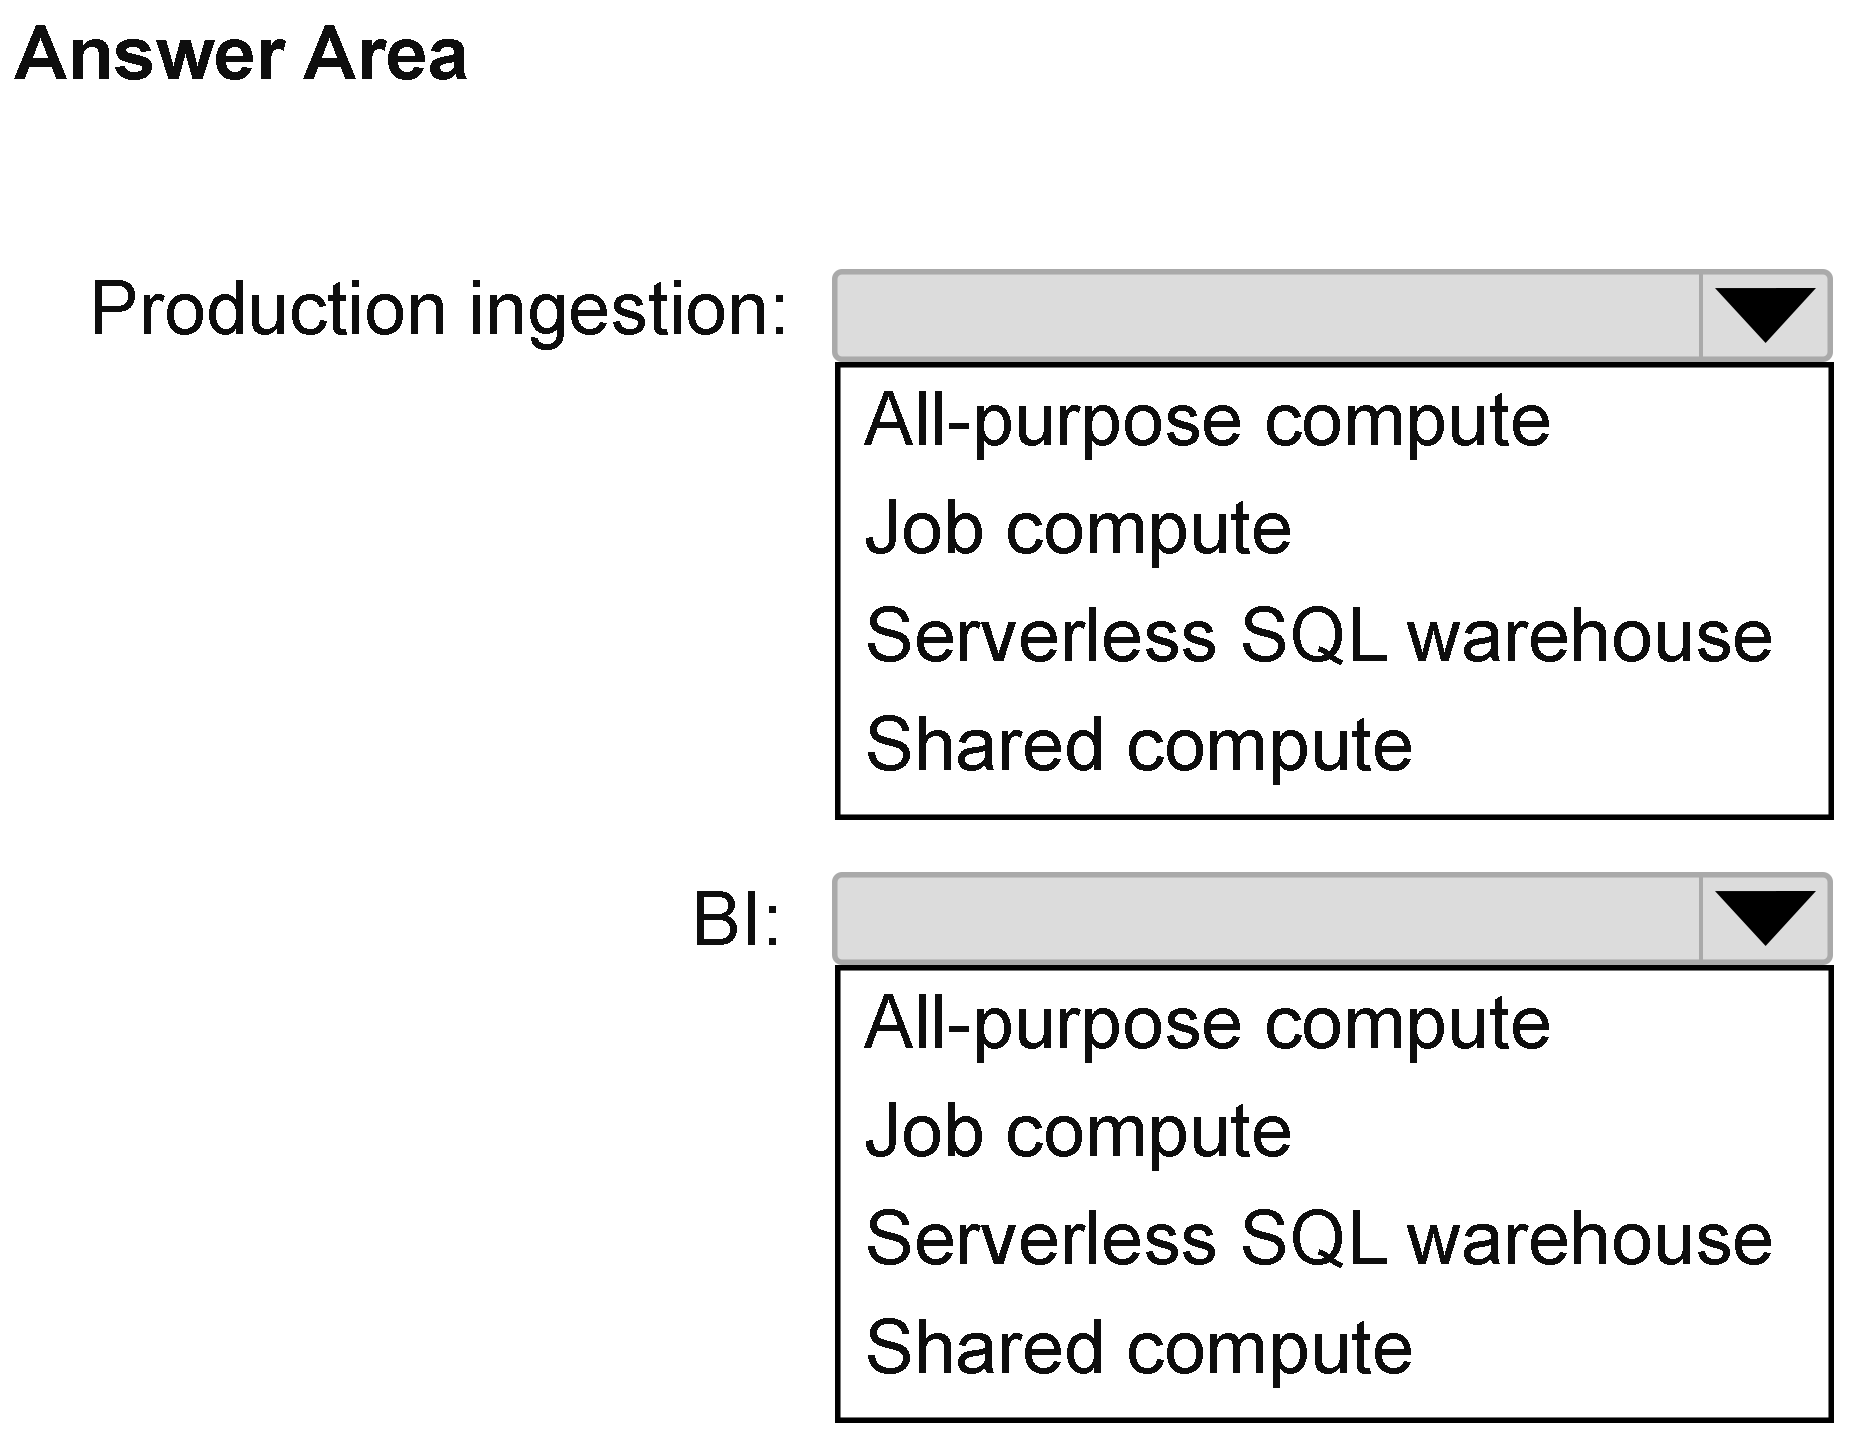
You need to recommend a compute type for the production ingestion workloads and BI workloads. The solution must meet the environment and compute requirements.
What should you recommend for each type of workload? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Key Takeaways
The main trap is selecting All-Purpose Clusters for both; they fail to provide the necessary isolation for production pipelines and lack the specific optimization for concurrent BI querying that SQL warehouses offer.
This page explains why Azure Databricks Jobs compute is the correct choice for production ingestion workloads requiring autoscaling and isolation, while SQL warehouses are recommended for BI workloads needing fast, consistent SQL performance.
Common mistake: Learners often select All-Purpose Clusters for ingestion because they are familiar with interactive development. This fails because all-purpose clusters share resources, cannot be easily scaled independently for batch jobs, and do not provide the strict isolation required for production workloads.
Expert Analysis
The scenario presents two distinct workload types with conflicting compute requirements: production ingestion and business intelligence (BI). The solution must isolate these workloads while adhering to specific operational constraints defined in the technical requirements.
For production ingestion, the requirements specify that pipelines must run as "scheduled, non-interactive pipelines" rather than on shared interactive clusters. They must also support automatic scaling during telemetry spikes and handle schema drift via Structured Streaming. In Azure Databricks, Jobs compute (specifically Job Clusters) is designed for this purpose. Unlike all-purpose clusters which are shared and interactive, job clusters are ephemeral, isolated, and optimized for automated, scheduled tasks. Crucially, Jobs compute supports autoscaling, allowing it to scale up during peak telemetry loads from IoT sensors and scale down when idle, thus meeting the requirement for efficient resource usage and isolation from development activities.
For BI workloads, the primary requirement is "fast and consistent performance" for SQL-based queries. Azure Databricks provides SQL warehouses specifically for this use case. SQL warehouses are multi-user SQL analytics endpoints that separate storage from compute, ensuring that BI queries do not interfere with data engineering pipelines. They offer high concurrency and performance tuning features tailored for dashboards and ad-hoc analysis, unlike general-purpose clusters which are less optimized for concurrent SQL query execution.
Therefore, the correct mapping is:
- Production Ingestion -> Jobs compute
- BI Workloads -> SQL warehouses
Official Reference
- https://learn.microsoft.com/en-us/azure/databricks/compute/
- https://learn.microsoft.com/en-us/azure/databricks/sql/
- https://learn.microsoft.com/en-us/azure/databricks/workflows/jobs/
These links open the official vendor documentation in a new tab.
Exam Strategy
When asked to choose compute types, always map the workload's interaction pattern (interactive vs. non-interactive) and performance needs (concurrency vs. throughput) to the service capabilities. For production pipelines, look for keywords like 'scheduled', 'non-interactive', and 'isolated' which point to Jobs. For BI/Analytics, look for 'SQL', 'dashboard', or 'concurrent users' which point to SQL Warehouses. Avoid All-Purpose Clusters for production unless explicitly stated as a temporary measure.
Frequently Asked Questions
Why can't we use All-Purpose Clusters for production ingestion?
What is the benefit of using SQL Warehouses over standard clusters for BI?
Discussion 1 contributions
Compiled from public community threads and reader submissions, lightly edited for clarity. Handles and vote tallies are shown as recorded, and comments reflect the views of individual contributors.
From public community threads 1
-
Raja419 👍 11. Production ingestion: Jobs compute with autoscaling - Runs scheduled, non-interactive workloads. - Supports automatic scaling during telemetry spikes. - Isolates production workloads from development activities. - Avoids using shared all-purpose clusters. - Integrates with job orchestration and retry mechanisms. 2. BI workloads: SQL warehouses - Designed for SQL queries and BI workloads. - Provides fast and consistent query performance. - Serverless SQL warehouses reduce infrastructure administration. - Supports BI integrations such as Power BI.
Reader comments & corrections
No reader corrections yet — spotted an error or have a note? Share it below.