Identifying Data Quality Issues in Initial Analysis
A data analyst is working on an initial analysis of the data set in the following table:
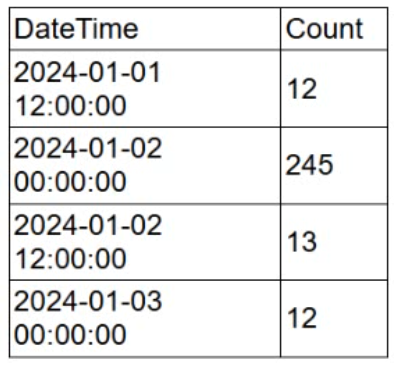 Which of the following issues should the analyst flag in the data report?
Community Insight
The core concept is identifying anomalies; the common trap is confusing general data integrity issues like duplication with statistical outliers.
This question tests the ability to identify data quality issues during initial analysis, specifically focusing on recognizing outliers that skew results.
Analysts often select 'Duplication' or 'Completeness' when they overlook values that are statistically extreme compared to the rest of the dataset.
Community Discussion (1 comments)
Comments & Corrections
No comments yet — spotted an error or have a note? Share it below.
Expert Analysis
Why the Answer Is Correct
An outlier is a data point that differs significantly from other observations in the dataset. During an initial analysis, flagging outliers is crucial because they can disproportionately affect statistical models and lead to inaccurate conclusions if not addressed.Why the Other Options Are Wrong
While completeness (missing data), mismatch (format inconsistencies), and duplication (repeated records) are valid data quality concerns, the specific context of "initial analysis" typically prioritizes identifying extreme values that distort the central tendency or variance of the data before cleaning structural issues.Community Comment Notes
Community feedback confirms that the correct answer is B, noting that outliers represent values significantly different from others. One commenter emphasized that these unusual values must be flagged to ensure accuracy in subsequent analysis steps.Exam Strategy
When reviewing data for initial analysis, always look for extreme values first. Outliers can masquerade as valid data but often indicate errors or rare events that require special handling.
Frequently Asked Questions
Why is an outlier more critical than duplication in initial analysis?
Outliers can drastically skew statistical measures like mean and standard deviation, leading to incorrect model training or insights.
Related Analysis
Practice All DA0-002 Questions
Access 100 questions with complete answers and detailed explanations.
View Full DA0-002 Practice Test →